Xelta Prism combines shoppable video tagging, interactive commerce overlays and scene-level intelligence to support product discovery within video workflows.
Xelta Prism brings shoppable video tagging and interactive commerce tools closer to scene-level video intelligence, giving brands and content teams a new way to think about products inside video.
Xelta is extending its video intelligence capabilities into commerce-focused workflows through Xelta Prism, where tools for understanding video scenes sit alongside features such as Shoppable Video Tagger and Interactive Commerce Overlays.
The idea is different from simply generating another product video.
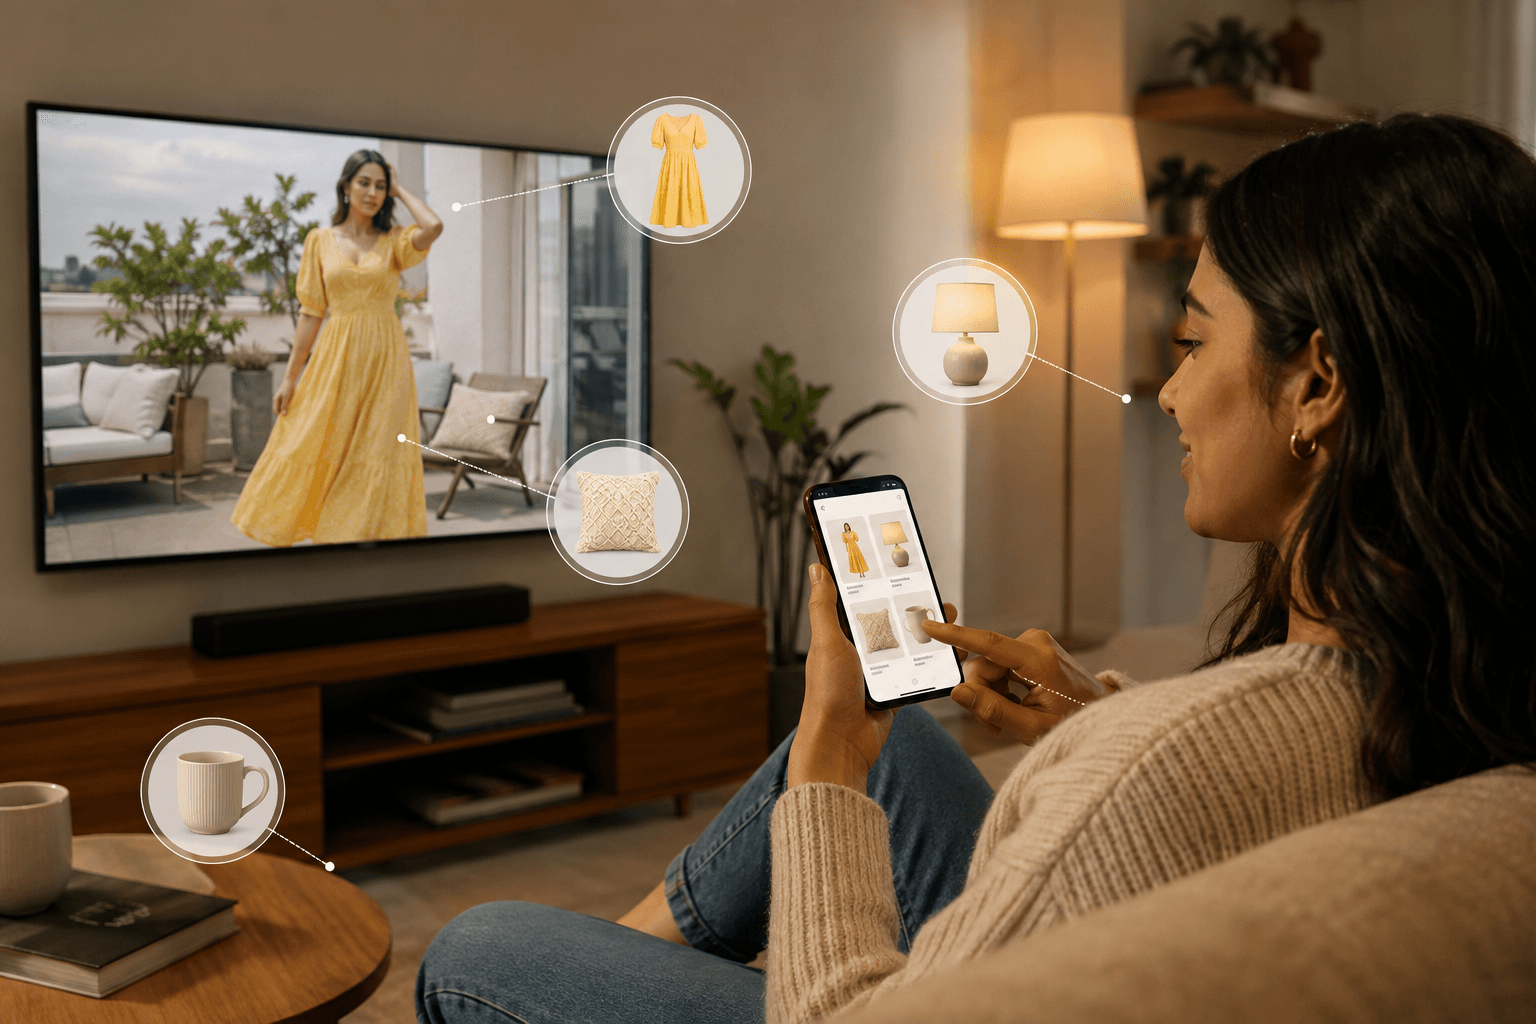
A piece of footage may already contain clothing, furniture, electronics, beauty products, food, accessories or other objects that matter to a viewer. The harder question is how brands and content teams make those moments easier to work with after the video has already been created.
Xelta Prism approaches that problem by bringing commerce-focused tools into the same environment as Deep AI Semantic Search, Deep Semantic Descriptors and Scene Level Tagging.
When the Product Is Already Inside the Scene
Most video workflows treat the finished video as the end product.
For commerce teams, however, the video may also contain useful product moments that could support discovery, promotion or future campaign work.
Xelta Prism currently groups Shoppable Video Tagger under its monetization, brand solutions and advertising capabilities. It also lists Interactive Commerce Overlays, giving the platform an explicit commerce-oriented layer within its wider video workflow.
This creates an interesting shift in how existing footage can be approached.
Instead of thinking only about where a product appears in a video, teams can begin thinking about how that appearance could become part of a more interactive content experience.
Xelta does not publicly state that Prism automatically identifies every product shown on screen or links every detected object to a purchase page. Its public interface confirms the availability of shoppable tagging and commerce overlay capabilities, but does not publish those implementation details.
Scene Intelligence Gives Commerce More Context
A product does not appear in isolation.
It appears in a scene, alongside people, places, actions and other visual information.
That is where Xelta Prism's wider video intelligence layer becomes relevant. The platform lists Scene Level Tagging, Deep Semantic Descriptors and Deep AI Semantic Search among its cognitive analytics and semantic intelligence capabilities.
For content teams, this means the commerce workflow sits alongside tools intended to describe and organize what is happening inside video.
That is different from manually going through footage only to remember that a certain jacket appeared at 12 minutes or that a particular product showed up briefly in the background of a campaign video.
The broader direction is toward making the contents of video easier to understand and work with at the scene level.
Video Commerce Without Turning Every Frame Into an Advertisement
Making video shoppable does not necessarily mean covering the screen with sales messages.
In practice, too many commercial elements can make a piece of content harder to watch.
Xelta Prism's commerce capabilities are more interesting when considered as tools that give brands options around relevant product moments rather than requiring every scene to become promotional.
The platform also lists Contextual Ads Match within its monetization and advertising tools.
That places shoppable tagging inside a broader set of capabilities related to content context, advertising and brand use.
Xelta does not publicly provide performance claims for these features, such as increased conversion rates, click-through rates or sales. Those outcomes depend on the content, audience, product, placement and wider campaign strategy.
Existing Video Can Have More Than One Job
A campaign video may begin as brand content.
A creator video may start as entertainment.
A long-form production might not originally have been designed around commerce at all.
Once those videos exist, however, understanding the products and relevant scenes inside them can create additional ways for teams to work with the same footage.
That idea fits the broader direction of Xelta Prism. Its interface brings together creative deliverables, semantic intelligence, smart editing and monetization tools rather than treating each of those tasks as completely separate systems.
For marketers and creative teams, this can make existing video more useful beyond the moment it is first published.
A More Connected View of Video Intelligence and Commerce
Shoppable video is often discussed as a layer placed on top of content after production.
Xelta Prism points toward a more connected model, where understanding scenes and building commerce-focused experiences can exist within the same broader video intelligence workflow.
The combination of Shoppable Video Tagger, Interactive Commerce Overlays, Scene Level Tagging and semantic intelligence tools gives Xelta a foundation for video workflows that consider not only what viewers are watching, but also which parts of that content may be relevant for discovery and brand activity.
The important distinction is that Xelta is providing tools for these workflows rather than promising that AI can determine the commercial value of every object or scene automatically.
Human decisions still matter: which product should be highlighted, whether a commerce element belongs in the scene, what information should accompany it and whether the result improves or distracts from the viewing experience.
To explore Xelta's video intelligence tools, visit Xelta or learn more about Xelta Prism.
About Xelta
Xelta is an AI creative platform providing tools for video, images, AI filmmaking, advertising, voices and content creation. Xelta Prism extends the platform into video intelligence and content workflows that include semantic analysis, editing, creative deliverables and monetization-focused capabilities.
Media Contact
Xelta
Website: Xelta.ai
Press Releases: Xelta Press Releases