
The Ranking Opportunity Is Not the Conversion Button
The strongest 2026 angle is not claiming more search demand. It is solving the document-specific problems that generic converter pages ignore. For pdf to video ai, AI Video Creation workflows on Xelta are most useful when the team defines the a PDF document, destination, and approval rules before generating scenes. The content should be designed for the destination rather than converted mechanically.
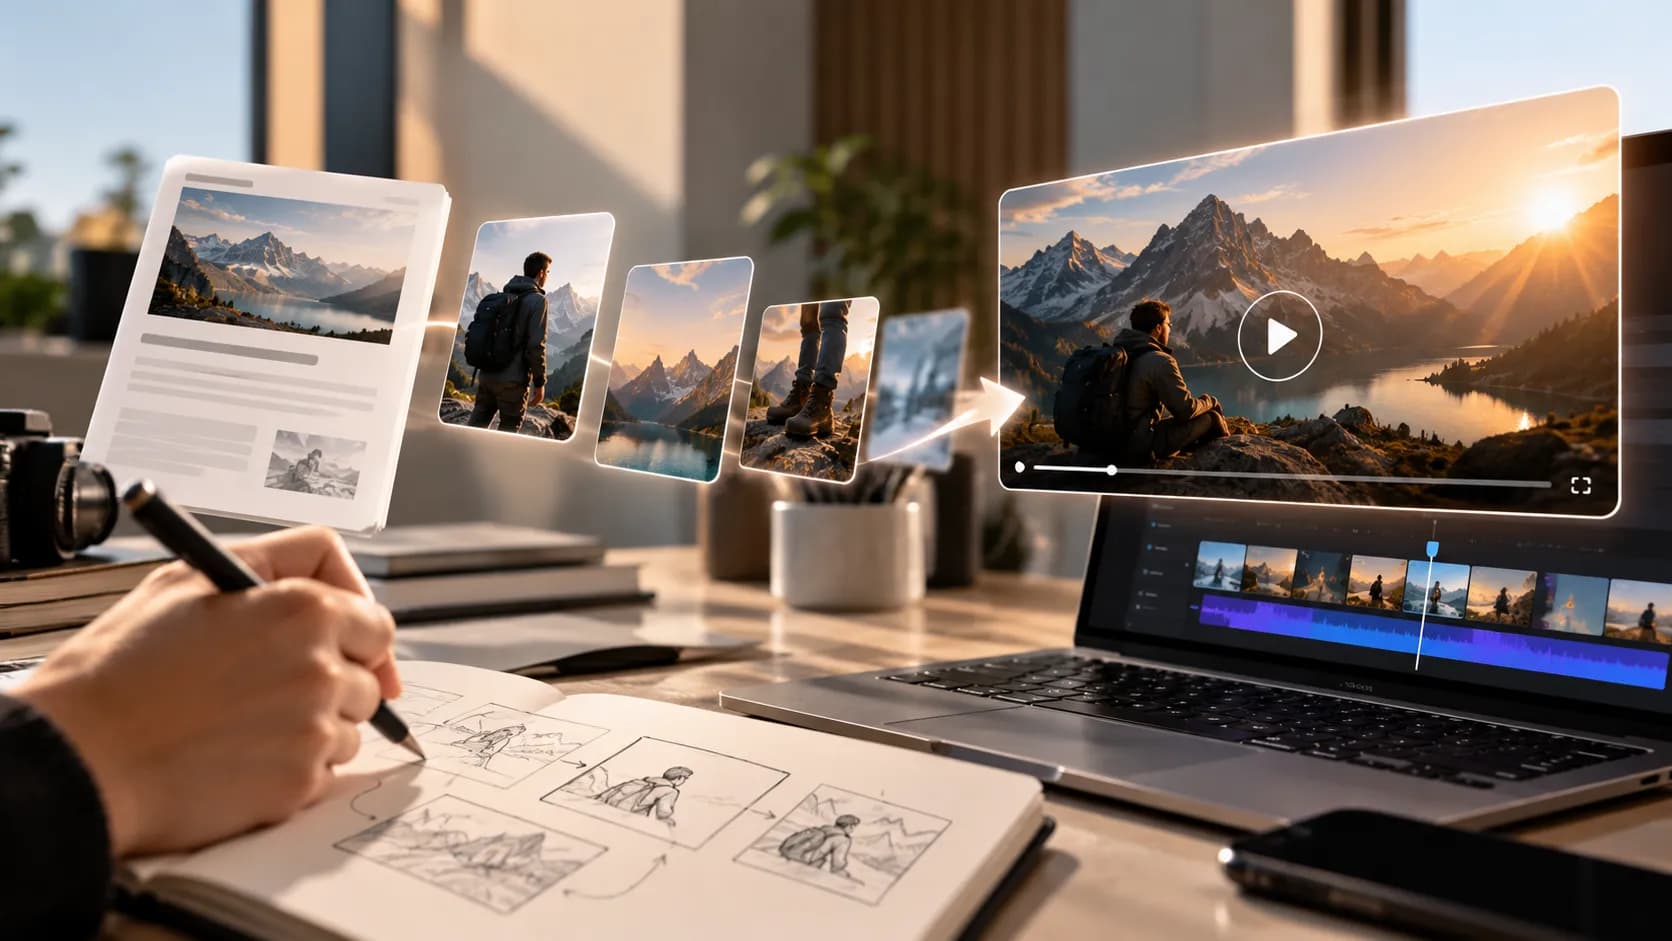
For SEO strategists, publishers, research teams, and product educators, the practical task is to turn a readable PDF, document type, audience question, evidence map, extraction check, and search-content plan into a useful video and supporting page that answer a specific query while preserving the document structure and evidence limits. The article uses the Extract-Question-Evidence-Format SEO Model to focus on document extraction, search intent, content gaps, answer design, evidence handling, and 2026 editorial differentiation. The Extract-Question-Evidence-Format SEO Model does not assume that generation clears rights, proves a claim, or removes the need for editing. Its main risk is that the conversion may inherit extraction errors and publish simplified answers without document context.
The Useful Answer Depends on the PDF Type
Validate the PDF structure, build the content around real reader questions, map important answers to source pages, and publish a transcript-rich resource that remains useful without the video player. Differentiation comes from document expertise and evidence handling, not invented keyword numbers. A pdf to video ai is useful when its drafts preserve the a PDF document, respond to targeted revision, and can be approved for one named destination.
Map Search Intent to the Document Job
Separate what must remain true from what may change creatively. The real question is how to build a differentiated PDF-to-video page for 2026 without inventing search volume or publishing generic conversion advice. Name the audience, final placement, allowed interpretation, protected facts, and reviewer. Then decide which parts of the a PDF document should be retained, shortened, rebuilt, or omitted. For pdf to video ai, this decision prevents a tool comparison from becoming a collection of attractive samples.
The Extract-Question-Evidence-Format SEO Model
The Extract-Question-Evidence-Format SEO Model uses five connected records. Source Control defines the approved a PDF document and protected details. The editorial map states the viewer question, message, and omissions. The generation plan translates the a PDF document plan into scenes, prompts, references, audio, and edit points. The assembly review tests the videos created from reports, guides, white papers, manuals, or other PDFs as a sequence. The release record identifies the approved pdf to video ai version, destination, limitations, and owner. The Extract-Question-Evidence-Format SEO Model records stop a a PDF document problem from being repaired in the wrong place. A source error should not be hidden with a new visual for videos created from reports, guides, white papers, manuals, or other PDFs.
Validate the PDF Before Writing the Video Brief
Check whether the document is text-based, scanned, protected, multi-column, table-heavy, image-heavy, or missing pages. Review extraction quality for headings, lists, footnotes, captions, and reading order. Bad extraction creates bad summaries and false confidence. Input: The source PDF and an extraction preview. Output: A document-quality note with known extraction limits. Review: Compare a sample against the original pages. Next: Choose a safe extraction and review method.
Build Questions From Real Document Friction
Identify the decisions readers struggle to make: definitions, steps, eligibility, comparisons, exceptions, calculations, or implementation. Use those questions to plan the video, not the PDF page count. Question-led structure matches practical search intent. Input: The document outline, support questions, and target audience. Output: A prioritized question map. Review: Confirm that the PDF actually answers each question. Next: Assign one video or chapter format per question.
Attach Evidence and Limitations to Every Answer
Record the page, section, table, or note supporting each answer. Keep dates, jurisdictions, assumptions, and exceptions visible. Do not present a simplified video as a complete substitute for the document. Evidence mapping protects meaning during compression. Input: The question map and source PDF. Output: An answer-to-source table with limitation notes. Review: Check the final script against the source pages. Next: Create visuals and captions from the approved answer.
Publish a Video Page That Can Stand Without the Player
Add a direct answer, useful transcript, chapter headings, source context, accessibility text, related internal links, and a clear document relationship. The page should remain helpful when the video cannot play. Search value comes from the complete resource, not only the media file. Input: Approved video, transcript, source notes, and page outline. Output: A publishable resource page. Review: Verify visible content matches structured data. Next: Update the page when the source PDF changes.
A Compliance Guide Turned Into a Search Content Hub
Picture a team with one source and several destinations: a B2B payments company adapting a 40-page compliance guide into one overview video, five question-led clips, and an indexed transcript hub. The pdf to video ai team first identifies protected facts in the a PDF document and one viewer outcome. It then creates a source map, a Extract-Question-Evidence-Format SEO Model plan, and a named checklist for videos created from reports, guides, white papers, manuals, or other PDFs. Early pdf to video ai drafts are assembled before every detail is polished, so a PDF document sequence problems appear while they are still inexpensive to change. This a PDF document scenario is a worked example, not a performance claim. Reviewers should reject any videos created from reports, guides, white papers, manuals, or other PDFs draft that changes important information, hides a limitation, or requires more repair than a simpler method.
Generic Converter Page Versus Document-Specific Resource
The pdf to video ai options below solve different production problems. Compare them using a PDF document fidelity, control, review effort, editability, and destination fit. For videos created from reports, guides, white papers, manuals, or other PDFs, the strongest method preserves required information and reaches approval without hiding repair work.
SEO Gaps That Make PDF-to-Video Pages Thin
The most damaging failure patterns are targeting the broad keyword with a generic upload-and-convert page, trusting extracted text without checking tables and reading order, creating one long summary for every document type, hiding page references and limitations during simplification, and publishing a video with no transcript or standalone answer. For pdf to video ai, these errors make the videos created from reports, guides, white papers, manuals, or other PDFs harder to verify and teach the team very little. Record the failure at its Extract-Question-Evidence-Format SEO Model stage: source, brief, prompt, generation, edit, or release.
Editorial Signals That Make the Page More Useful
A stronger operating standard is to segment content by PDF type and reader task, validate extraction before summarization, build videos around real questions rather than page count, map important answers back to document locations, and publish transcripts and direct answers that remain useful without playback. For pdf to video ai, these controls protect the relationship between the a PDF document and the final videos created from reports, guides, white papers, manuals, or other PDFs.
Where Xelta Microcourse Fits in Document Education
Xelta can enter after the team has prepared the a PDF document, the production map, and the acceptance criteria. The core video generator can support initial scene creation, while a structured learning flow for converting long documents into smaller explanatory video chapters offers a more specific route for this article's workflow. The pdf to video ai user still chooses the a PDF document, approves instructions, compares drafts, and finishes the videos created from reports, guides, white papers, manuals, or other PDFs edit.
The Extract-Question-Evidence-Format SEO Model advantage is that exploration and variation happen closer to the approved a PDF document. That does not make every videos created from reports, guides, white papers, manuals, or other PDFs detail accurate. Product facts, speaker identity, rights, accessibility, continuity, and the final pdf to video ai placement remain human review responsibilities.
What a Search Team Should Expect From the First Draft
A useful first session begins with a readable PDF, document type, audience question, evidence map, extraction check, and search-content plan. The user turns the a PDF document into one narrow pdf to video ai assignment and generates a small comparison set. The first videos created from reports, guides, white papers, manuals, or other PDFs draft is inspected for direction and source fidelity before polish. During Extract-Question-Evidence-Format SEO Model revision, accepted elements stay fixed while one important variable changes.
Xelta video learning resources can support learning for pdf to video ai, but project approval must come from the user's own a PDF document and checklist. The pdf to video ai learning curve is mainly editorial: deciding what the viewer needs from the a PDF document, writing visible instructions, and diagnosing defects. The final videos created from reports, guides, white papers, manuals, or other PDFs should be tied to one approved use and version.
Design the Transcript for Humans and Retrieval Systems
For search and generative retrieval, a pdf to video ai page should answer the central question early, define the a PDF document input and videos created from reports, guides, white papers, manuals, or other PDFs output, and explain the Extract-Question-Evidence-Format SEO Model with task-specific headings. Keep the pdf to video ai transcript, visible article, FAQs, and structured data aligned. Label a PDF document examples clearly and avoid invented search volume, performance numbers, legal conclusions, or tool capabilities. This guidance is designed for SEO strategists, publishers, research teams, and product educators and uses a reproducible editorial method: controlled source material, explicit transformation choices, staged review, and a documented release decision. The Extract-Question-Evidence-Format SEO Model does not guarantee ranking, citation, or commercial results.
Compete on Usefulness, Not Unsupported Volume Claims
Begin with one approved a PDF document, one viewer job, and one destination. Use the Extract-Question-Evidence-Format SEO Model to create a small draft set, record what changed, and approve only the version that preserves the required information. For pdf to video ai, the next practical step is to open Xelta Microcourse Flow and test the topic-specific workflow with controlled a PDF document material.