
Turn a Voice Track Into Video: Choosing Visuals, Pacing and Scene Changes
Work on building video around an existing voice track can fail before generation begins. An unclear audience, mixed objectives, or incomplete source assets create problems that no model can reliably solve later for podcasters, educators, and marketers who already have approved audio.
For podcasters, educators, and marketers who already have approved audio, the voice track should control the edit rhythm while visuals provide context and proof. A useful project begins with a cleaned voice track, transcript, timing markers, visual references, and channel format and aims for a visual sequence paced to speech without distracting from the message. The central risk is changing visuals at every sentence or using literal imagery that competes with the voice. Xelta's AI creation platform can support building video around an existing voice track, but the brief, source approval, and publishing judgment must remain explicit for podcasters, educators, and marketers who already have approved audio.
This article explains how to plan building video around an existing voice track, what to test, where errors appear, and how to review the work without relying on unsupported performance claims.
What to prioritize before choosing a workflow for building video around an existing voice track
For podcasters, educators, and marketers who already have approved audio, evaluate building video around an existing voice track by pacing that follows meaning rather than word count, correction control, and review fit. Begin with a cleaned voice track, create one test draft, and inspect pacing that follows meaning rather than word count. The Xelta AI video generator can support building video around an existing voice track, while final approval remains a human decision.
How the core mechanism works in practice for building video around an existing voice track
The mechanism behind building video around an existing voice track is a chain of interpretation, creation, assembly, and review. The system interprets a cleaned voice track, transcript, timing markers, visual references, and channel format, produces candidate visual or edit decisions, and turns them into a visual sequence paced to speech without distracting from the message. Each stage in building video around an existing voice track can introduce drift, so podcasters, educators, and marketers who already have approved audio need a visible handoff between source, draft, revision, and approval. In this topic, the most useful control is pacing that follows meaning rather than word count. That control lets a reviewer identify the exact weakness affecting pacing that follows meaning rather than word count instead of rejecting the entire result.
The requirements that deserve a real test for building video around an existing voice track
Evaluate building video around an existing voice track with a representative task, not a showcase prompt. The test should reveal how the system handles transcript accuracy, beat timing, visual hierarchy, scene duration, captions, and audio peaks. For building video around an existing voice track, ask what happens when one scene is wrong, one asset changes, or one reviewer requests a different format. A practical building video around an existing voice track setup should preserve approved facts, accept precise corrections, and keep versions understandable. For podcasters, educators, and marketers who already have approved audio, faster drafting matters only when the correction path does not create more work than it removes.
A production path built around reviewable decisions for building video around an existing voice track
-
Clean and transcribe the audio Tie building video around an existing voice track to a real viewer or publishing decision. Use a cleaned voice track, transcript, timing markers, visual references, and channel format. Produce a one-sentence objective and named reviewer.
-
Mark topic and emphasis beats Remove ambiguity from a cleaned voice track, transcript, timing markers, visual references, and channel format before production begins. Use the approved result of step 1. Produce a clean, approved source package.
-
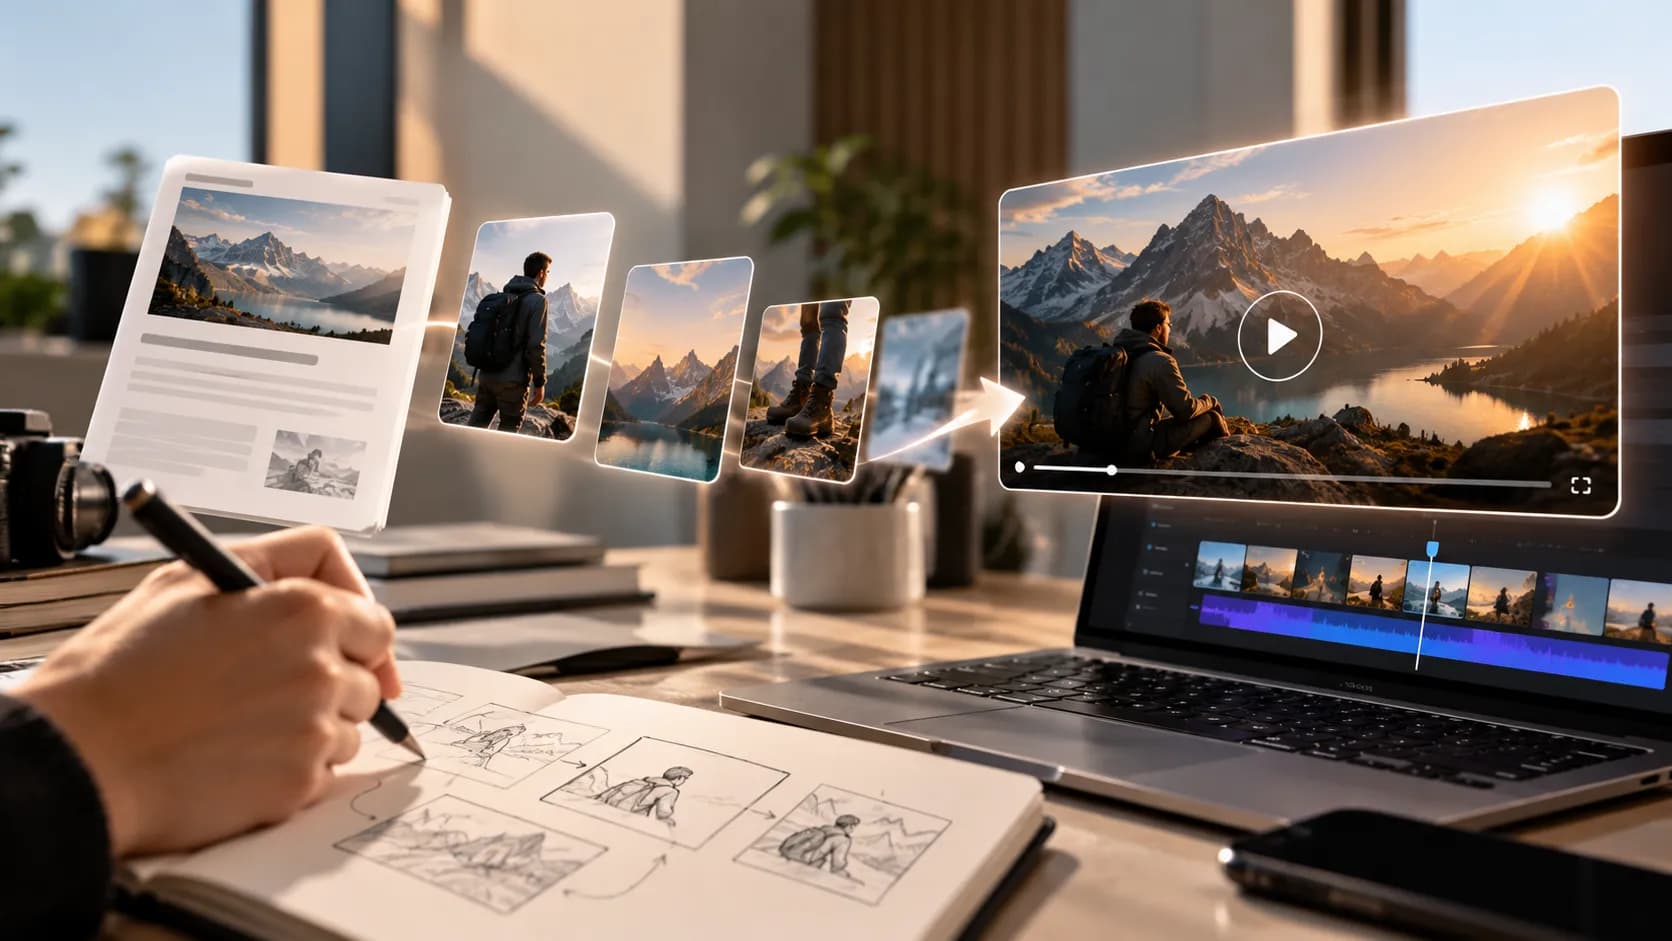
Assign a visual purpose to each beat Make a visual sequence paced to speech without distracting from the message assessable scene by scene. Use the approved result of step 2. Produce a timed scene or edit map.
-
Choose recurring visual motifs Expose the hardest risk before it reaches the full timeline. Use the approved result of step 3. Produce a representative building video around an existing voice track test that exposes the hardest constraint.
-
Generate and time scenes Compare changes against pacing that follows meaning rather than word count rather than novelty. Use the approved result of step 4. Produce a small set of deliberately different versions.
-
Review with sound on and muted Confirm transcript accuracy, beat timing, visual hierarchy, scene duration, captions, and audio peaks before release. Use the approved result of step 5. Produce an approved a visual sequence paced to speech without distracting from the message master plus a record of rejected issues.
Worked example for podcasters, educators, and marketers who already have approved audio
Consider a 60-second expert commentary turned into a vertical video with restrained b-roll and on-screen keywords. The weak approach to building video around an existing voice track begins with a broad request for a polished video and leaves the system to invent missing context. That creates avoidable uncertainty around transcript accuracy, beat timing, visual hierarchy, scene duration, captions, and audio peaks.
A stronger approach starts with a cleaned voice track, transcript, timing markers, visual references, and channel format. For building video around an existing voice track, the team defines one viewer outcome, tests the hardest requirement, and creates only enough variants to compare a real decision. The resulting a visual sequence paced to speech without distracting from the message is then reviewed against the source rather than against personal taste alone. This building video around an existing voice track example is a worked scenario, not a claim about guaranteed performance.
Mistakes that undermine pacing that follows meaning rather than word count
The first failure is changing visuals at every sentence or using literal imagery that competes with the voice. A second is changing the source, prompt, timing, and visual style at the same time; the team then cannot tell which change improved or damaged pacing that follows meaning rather than word count.
A stronger standard for repeatable output for building video around an existing voice track
Use a compact building video around an existing voice track brief with audience, outcome, source assets, duration, format, and reviewer. Break difficult work into testable parts, especially where pacing that follows meaning rather than word count can fail.
Comparing the available production approaches for building video around an existing voice track
A static waveform video may be suitable for a low-risk, isolated task. A rapid b-roll montage offers deeper control over one part of the job but may require manual handoffs. A editorial audio-led story is better when the team needs repeatable inputs, several versions, and a shared review path.
Choose the building video around an existing voice track route by correction cost, source sensitivity, and publishing risk. The best route for podcasters, educators, and marketers who already have approved audio is the one that protects pacing that follows meaning rather than word count with the least unnecessary movement between tools.
What to record during the pilot for building video around an existing voice track
Review this section for completeness before publishing.
Where Xelta enters the process for building video around an existing voice track
Xelta can enter after a cleaned voice track, transcript, timing markers, visual references, and channel format has been approved. A user working on building video around an existing voice track can choose a relevant video workflow, create a first direction, and prepare controlled alternatives while keeping the final decision outside generation. For building video around an existing voice track, Xelta's AI voice workflow is the most specific destination selected from the uploaded Xelta sitemap.
For building video around an existing voice track, Xelta's useful role is reducing repetitive setup when another scene, hook, format, or version is required. The team still needs to check transcript accuracy, beat timing, visual hierarchy, scene duration, captions, and audio peaks. Source quality and clear instructions remain decisive in building video around an existing voice track, and the first draft may require several focused revisions.
A realistic first creation cycle in Xelta for building video around an existing voice track
A first session would typically start with a cleaned voice track, transcript, timing markers, visual references, and channel format. For building video around an existing voice track, the user defines the intended output and channel, adds approved references, and creates a short representative draft. The first useful result should be complete enough to expose whether pacing that follows meaning rather than word count is holding up, not polished enough to bypass review.
Iteration in building video around an existing voice track should be controlled by changing one weak scene, timing decision, visual constraint, or format at a time. Podcasters, educators, and marketers who already have approved audio can use Xelta's YouTube channel as an additional learning touchpoint while building a building video around an existing voice track checklist, without treating the channel as proof of a specific product result.
Input: a cleaned voice track, transcript, timing markers, visual references, and channel format. Action: Create one representative direction for building video around an existing voice track. First draft: a visual sequence paced to speech without distracting from the message. Iteration: Correct the element that weakens pacing that follows meaning rather than word count. Human review: Check transcript accuracy, beat timing, visual hierarchy, scene duration, captions, and audio peaks. Final use: Publish only the approved a visual sequence paced to speech without distracting from the message in its intended channel.
Trust, rights, and final quality checks for building video around an existing voice track
Clear source truth usually matters more to building video around an existing voice track than prompt length.
Testing the hardest requirement first exposes the real correction cost in building video around an existing voice track.
Turn the first project into a useful system for building video around an existing voice track
The next useful move is to map the audio beats before generating any visuals. Use the building video around an existing voice track pilot to improve the brief, source package, and review criteria. Once the team can explain why the resulting a visual sequence paced to speech without distracting from the message passes the checks, it has a foundation that can scale without hiding quality problems.